Abstract

INoD teaser image

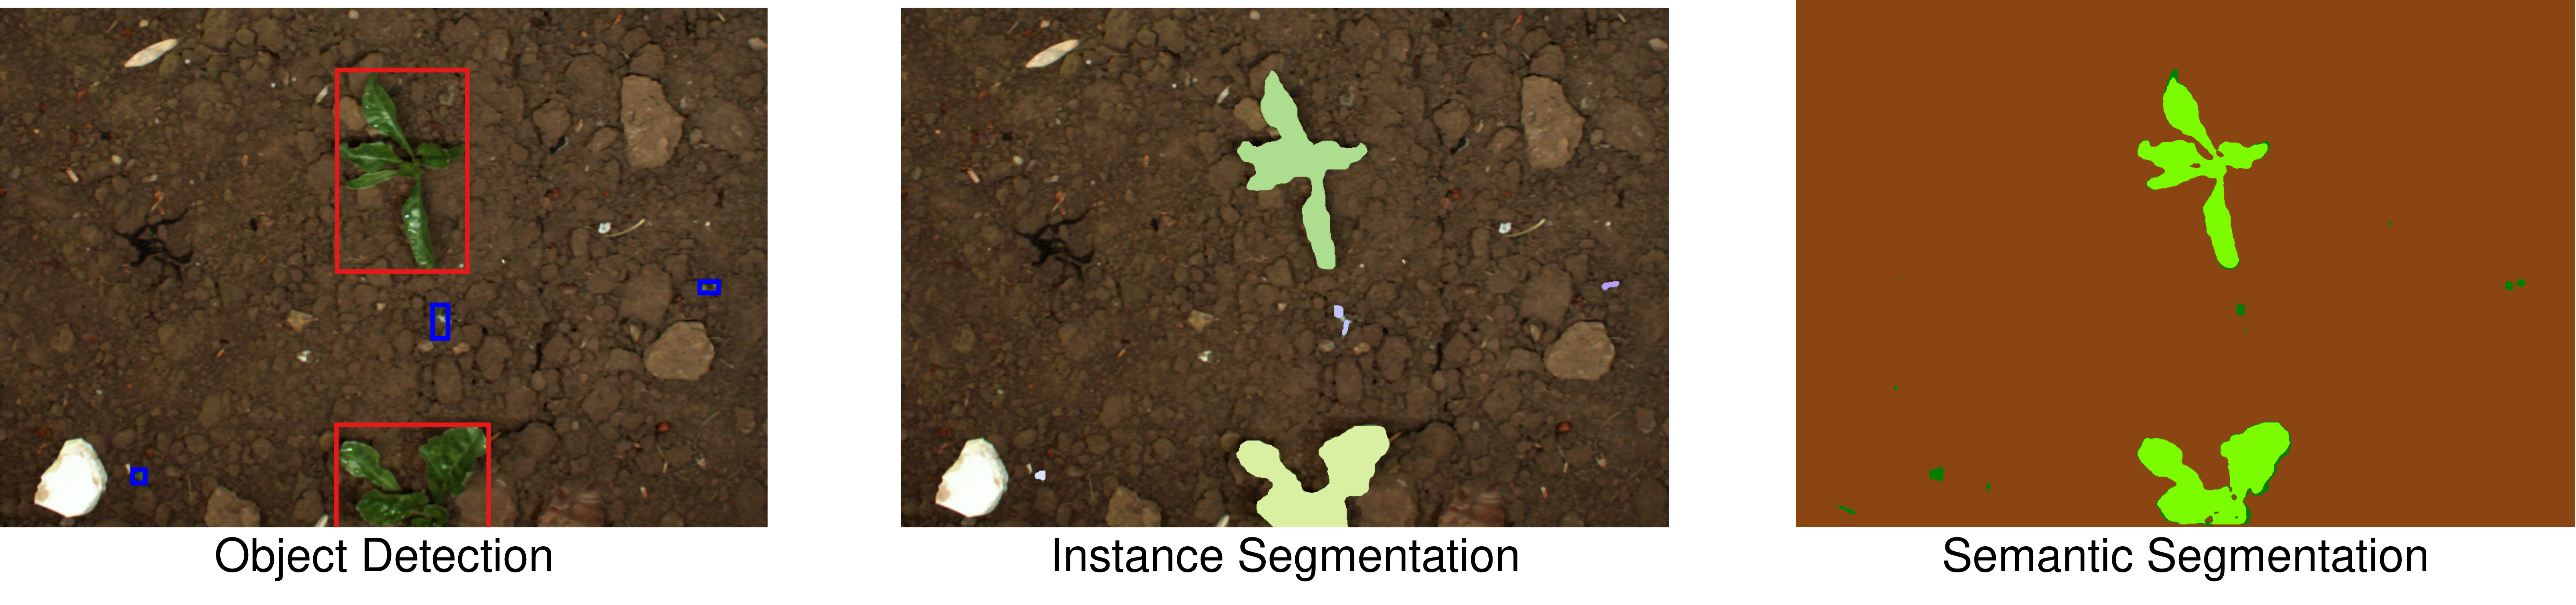
Perception datasets for agriculture are limited both in quantity and diversity which hinders effective training of supervised learning approaches. Self-supervised learning techniques alleviate this problem, however, existing methods are not optimized for dense prediction tasks in agriculture domains which results in degraded performance. In this work, we address this limitation with our proposed Injected Noise Discriminator (INoD) which exploits principles of feature replacement and dataset discrimination for self-supervised representation learning. INoD interleaves feature maps from two disjoint datasets during their convolutional encoding and predicts the dataset affiliation of the resultant feature map as a pretext task. Our approach enables the network to learn unequivocal representations of objects seen in one dataset while observing them in conjunction with similar features from the disjoint dataset. This allows the network to reason about higher-level semantics of the entailed objects, thus improving its performance on various downstream tasks. Additionally, we introduce the novel Fraunhofer Potato 2022 dataset consisting of over 16,800 images for object detection in potato fields. Extensive evaluations of our proposed INoD pretraining strategy for the tasks of object detection, semantic segmentation, and instance segmentation on the Sugar Beets 2016 and our potato dataset demonstrate that it achieves state-of-the-art performance.
Technical Approach

Why self-supervised representation learning in agricultural fields? Precision agriculture heavily relies on plant detection and segmentation, which is often challenging due to the varied appearance of plants throughout their growth cycle. Additionally, the lack of labeled datasets encompassing different crops hinders the development of fully-supervised plant detection and segmentation approaches. Self-supervised learning (SSL) techniques help combat this label deficiency by pretraining the network on pseudo labels obtained from self-derived pretext tasks before finetuning on the downstream target task. The pretraining step enables the network to learn the underlying semantics of the image, which helps it better adapt to a wide range of relevant tasks and datasets.

Existing SSL approaches in the agricultural domain are based on learning techniques tailored for ImageNet classification or rely on the color-susceptible NDVI metric. Our proposed self-supervised INoD approach demonstrates exceptional performance for a range of dense prediction tasks such as object detection, semantic segmentation, and instance segmentation.

INoD network architecture
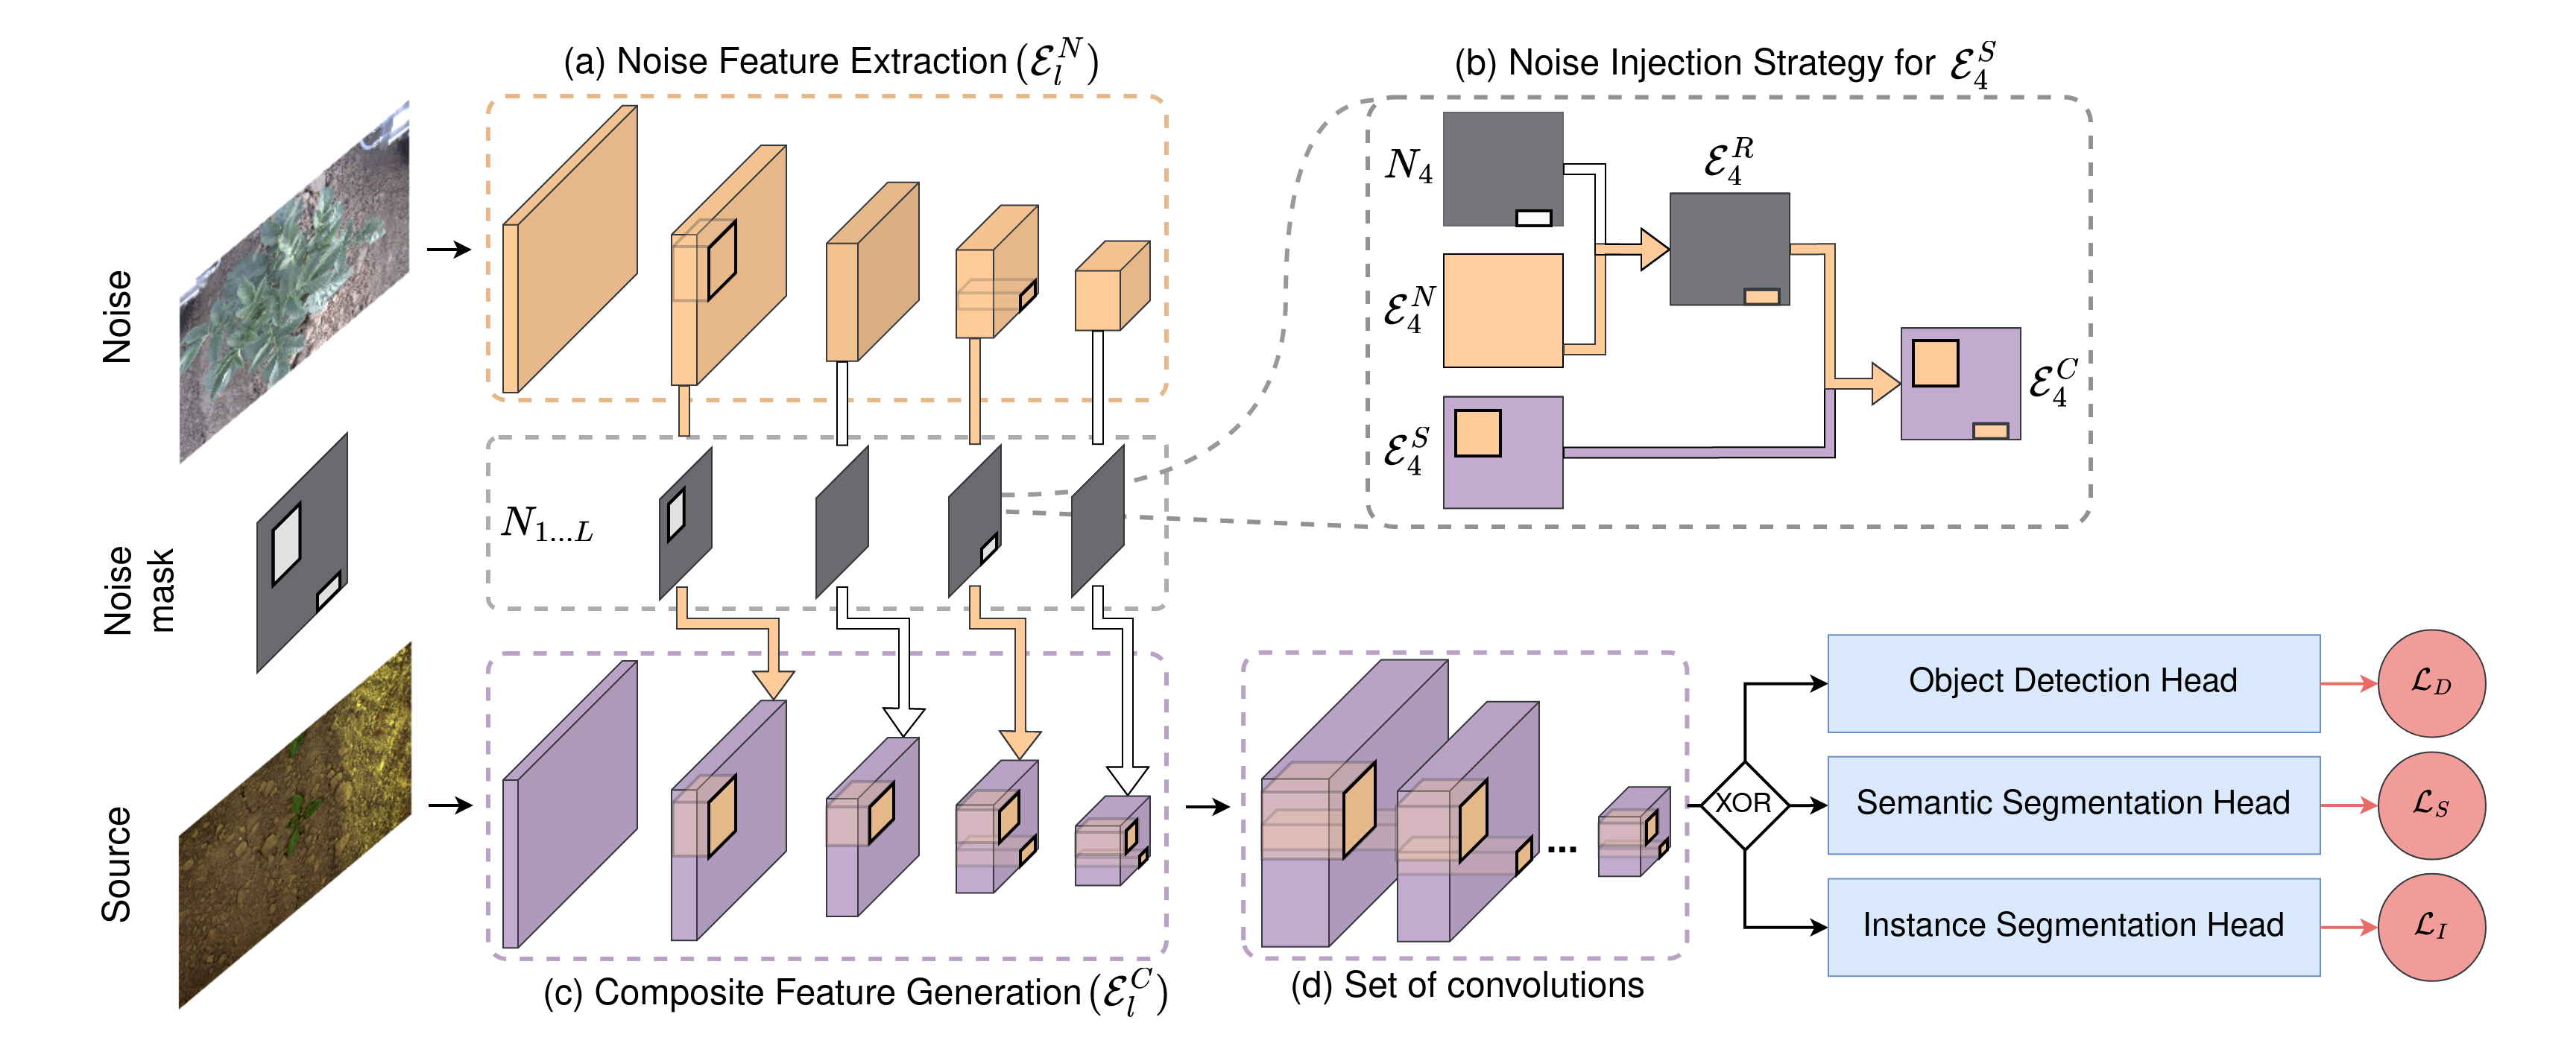
Figure: INoD merges features of images from two disjoint datasets during their convolutional encoding. The network is then trained end-to-end to determine the dataset affiliation with a semantic segmentation, instance segmentation, or object detection head.

The goal of injected feature discrimination is to make the network learn unequivocal representations of objects from one dataset while observing them alongside objects from a disjoint dataset. Accordingly, the pretraining is based on the premise of injecting features from a disjoint noise dataset into different feature levels of the original source dataset during its convolutional encoding. The network is then trained to determine the dataset affiliation of the resultant feature map, which enables learning rich discriminative feature representations for different objects in the image.

We use an off-the-shelf network backbone to compute multi-scale feature maps for the noise image {\(ε^N_1, ε^N_2, ..., ε^N_L\)} (Figure (a)). Second, we generate random layer-specific binary noise masks, \(N_{l}\), for each scale \(l\) to determine the spatial locations at which the noise features are injected into the source features. Third, we extract region-specific noise features, \(ε^R_l\), by multiplying each of the multi-scale noise features, \(ε^N_{l}\), with their corresponding layer-specific noise mask \(N_l\). After, we iteratively inject \(ε^R_l\) at equivalent locations in the source feature map \(ε^S_{l}\) to generate a composite feature map \(ε^C_{l} = f(ε^N_{l}, ε^S_{l}, N_{l})\) (Figure (b)). We then perform the subsequent source network traversal step of the backbone to generate the next level feature map \(ε^S_{l+1}\). Thus, noise injected in early feature maps is carried through higher layers of the network backbone as shown in Figure (c). Finally, we pass the composite feature maps through a set of convolutional layers to further entangle features and generate coherent multi-scale representations (Figure (d)). We then provide these feature maps as input to downstream task heads such as object detection, semantic segmentation, or instance segmentation to infer the dataset affiliation of the composite feature maps.

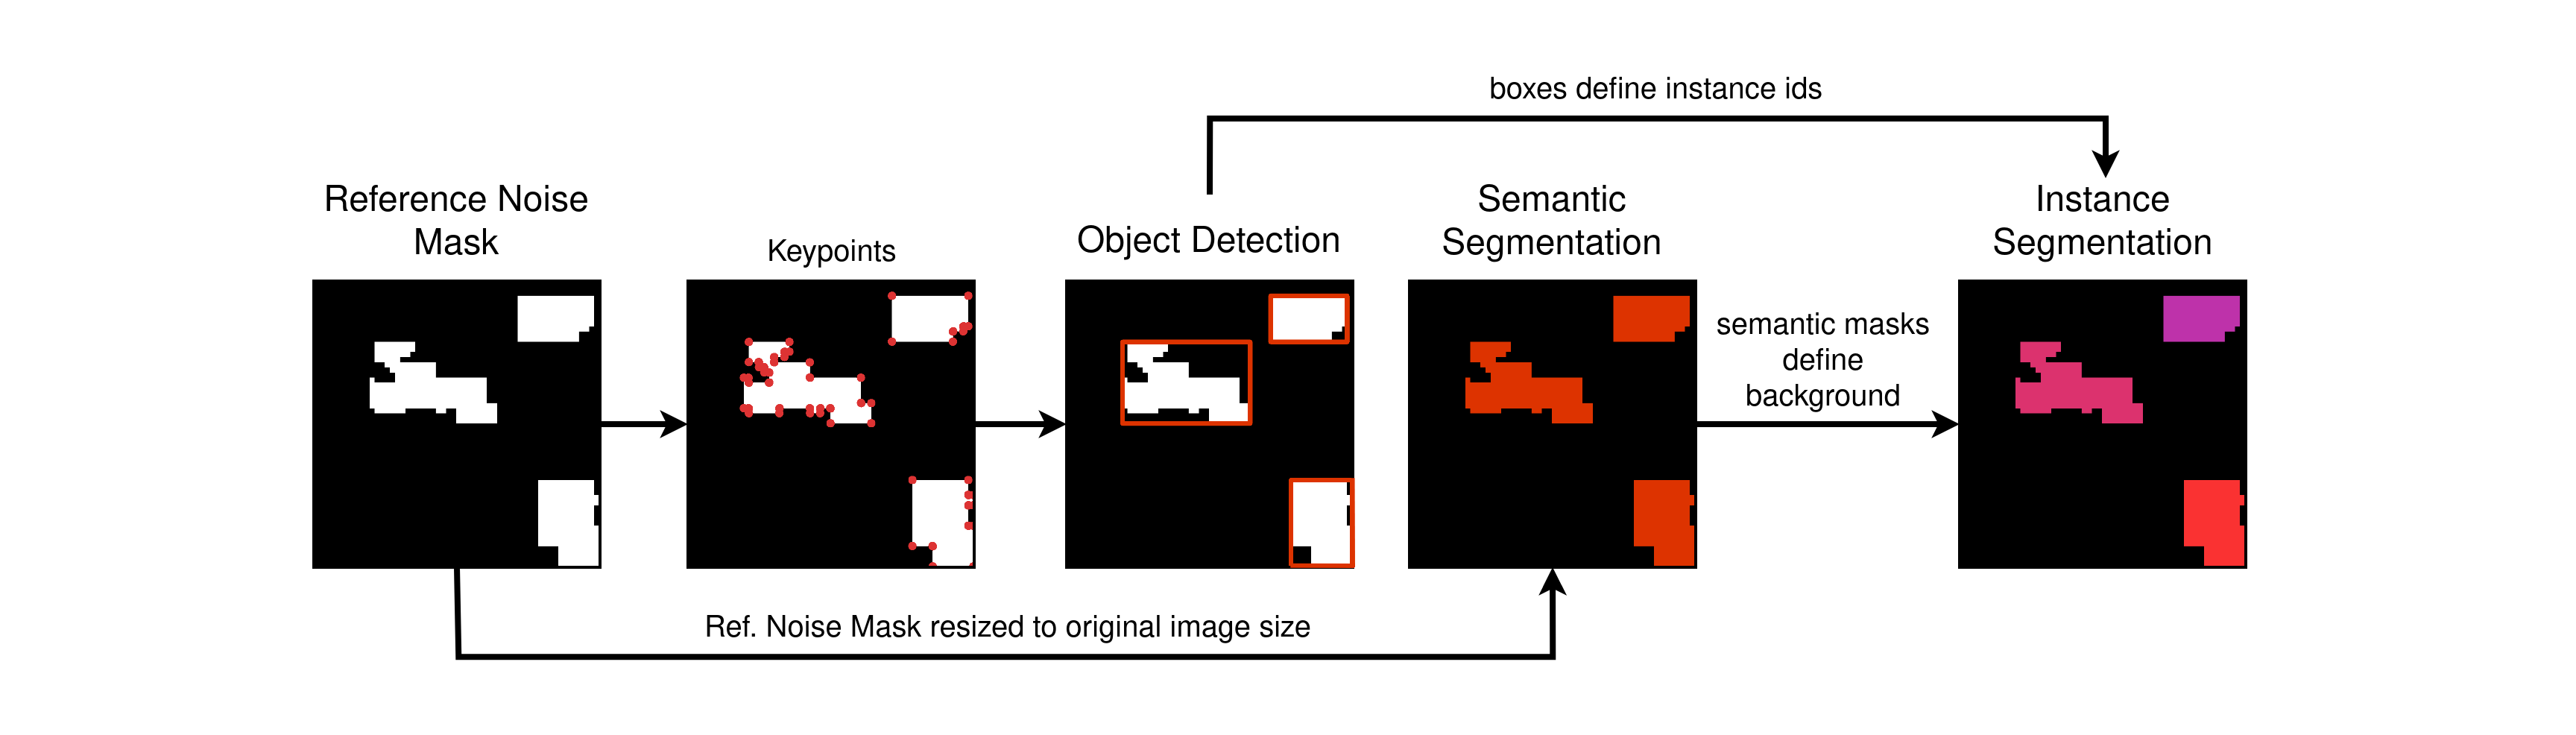
Task-specific ground truth label generation. We supervise the dataset affiliation of the composite feature map by generating task-specific pseudo labels which correspond to the downstream task.

Task-specific ground truth label generation
Figure: Visualization of pseudo label creation for each task.
  • Object detection: We generate these pseudo labels by first computing contours around non-zero elements in the noise mask and then drawing tight axis-aligned bounding boxes around them. Drawing boxes around contours instead of around every independent noise element allows us to generate diverse bounding box pseudo labels in terms of both box size and box scale, which improves the overall model performance.
  • Semantic segmentation: For the semantic segmentation task, we create the corresponding pseudo label by resizing the noise mask to the pre-determined output resolution using the nearest neighbor interpolation algorithm.
  • Instance segmentation: We compute the instance segmentation pseudo labels by first generating the bounding box pseudo labels and then post-processing them to extract the instance IDs of different elements in the noise mask. The post-processing step entails computing the non-zero elements within a bounding box and assigning a common instance label to all of them.

Video

Code

A software implementation of this project based on PyTorch can be found in our GitHub repository for academic usage and is released under the GPLv3 license. For any commercial purpose, please contact the authors.

Fraunhofer Potato Dataset

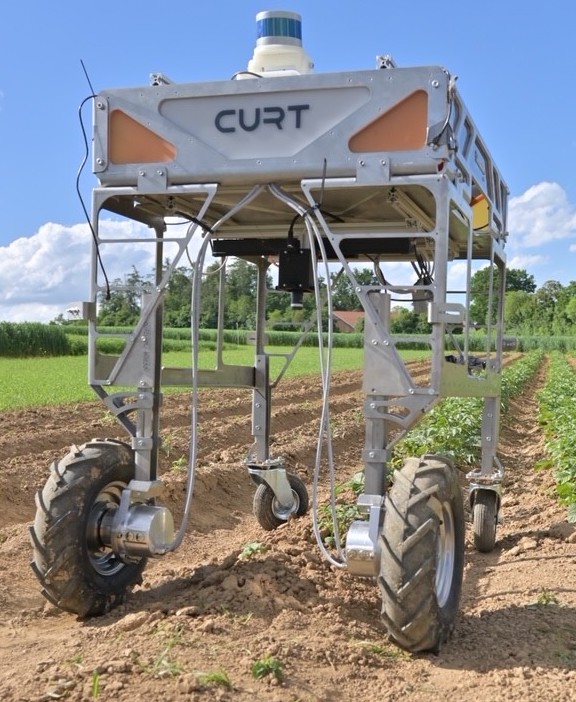
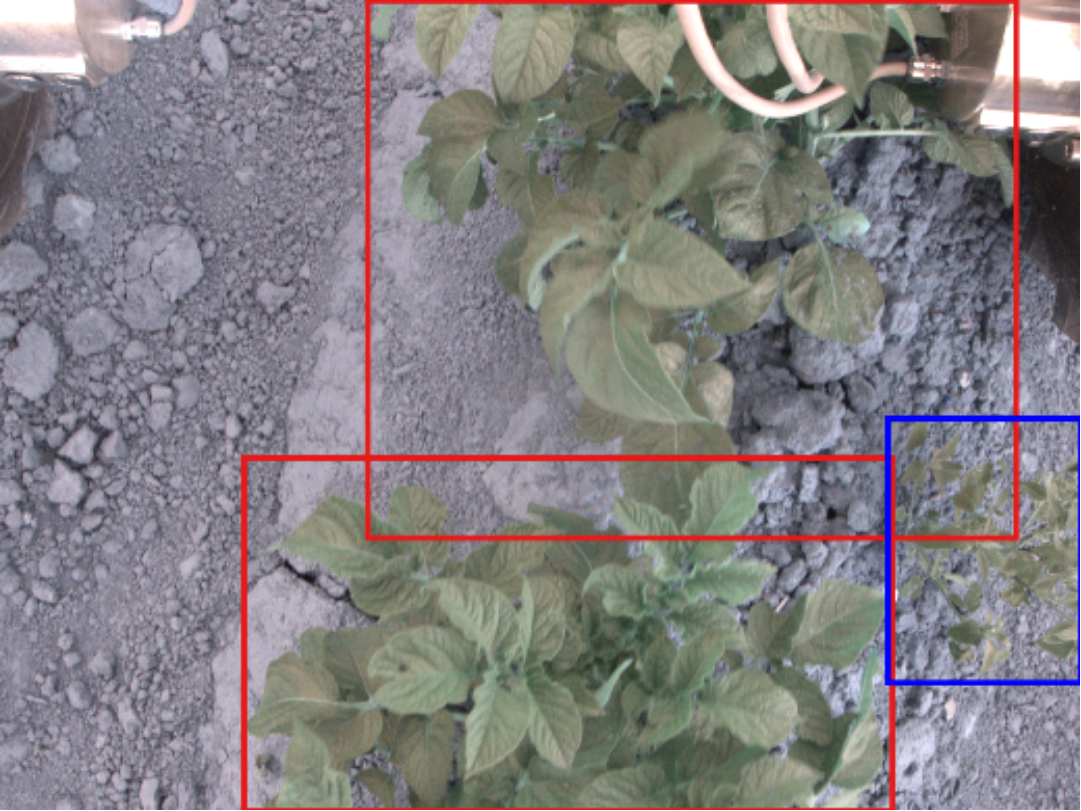
The agricultural robot CURT Dataset example 1 Dataset example 2

This is a recent dataset by Fraunhofer IPA which was recorded using an agricultural robot at a potato cultivation facility in the outskirts of Stuttgart, Germany. The robot depicted above comprises a Jai Fusion FS 3200D 10G camera mounted at the bottom of the robot chassis at a height of 0.8 m above the ground. The dataset contains 16,891 images obtained from two different stages in the farming cycle of which a subset of 1,433 images have been annotated with bounding box labels following a peer-reviewed process.

License agreement. The data is provided for non-commercial use only. By downloading the data, you accept the license agreement which can be downloaded here. If you report results based on the dataset, please consider citing the paper mentioned in the Publication section.

Publications

If you find our work useful, please consider citing our paper:

Julia Hindel, Nikhil Gosala, Kevin Bregler, and Abhinav Valada
INoD: Injected Noise Discriminator for Self-Supervised Representation Learning in Agricultural Fields
IEEE Robotics and Automation Letters (RA-L), vol. 8, no. 9, pp. 6013-6020, 2023.

(PDF(IEEE)) (PDF(ArXiv)) (BibTeX)

Authors

Julia Hindel

Julia Hindel

University of Freiburg

Nikhil Gosala

Nikhil Gosala

University of Freiburg

Kevin Bregler

Kevin Bregler

Fraunhofer IPA

Abhinav Valada

Abhinav Valada

University of Freiburg

Acknowledgment

This work was partly funded by the German Research Foundation (DFG) Emmy Noether Program grant number 468878300.